⚠️ Affiliate Disclosure: This post is not an affiliate associated review. It may become one in the future and this disclosure will reflect that. This does not affect my reviews and I only recommend tools I genuinely believe in.
Anthropic has released Claude Fable 5.2, its new top model for “the most ambitious, open-ended technical work”, alongside a restricted version called Claude Mythos 5.2. Announced on 9 November 2026, Fable 5.2 is available to all users and, according to Anthropic, its outputs are up to 30% faster than Fable 5.1’s. The surprise is Anthropic’s own advice: for most coding and knowledge work, it says to start with Claude Opus 5.5, not Fable.
What Is Claude Fable 5.2?
Claude Fable 5.2 is the successor to Claude Fable 5.1, which launched in September. Anthropic says it improves on coding, reasoning and vision, and that it “communicates more clearly”. Here are the basics from Anthropic’s models overview:
| Claude Fable 5.2 | Detail |
|---|---|
| API price | $8 per million input tokens, $40 per million output tokens |
| Fast mode | $16 input / $80 output, for up to 2.5x faster token generation |
| Context window | 1M tokens |
| Maximum output | 128K tokens |
| API model ID | claude-fable-5-2 |
| Default effort | Medium in the Claude apps and Claude Code; high on the API |
For comparison, Claude Opus 5.5 costs $4 input and $20 output per million tokens, so Fable 5.2 is twice the price of Opus on the API. Anthropic says Fable 5.2 is available on all platforms, including Amazon Web Services, Google Cloud and Microsoft Azure.
What Is the Difference Between Claude Fable 5.2 and Mythos 5.2?
As with the 5.1 release, Anthropic says “Claude Fable and Claude Mythos are the same underlying model”. The difference is the safeguards:
- Claude Fable 5.2 has cyber and biology safeguards, which is what lets Anthropic open it to everyone. Anthropic says those safeguards “will block most cybersecurity-related tasks”, but are as robust as Fable 5.1’s with fewer unnecessary blocks.
- Claude Mythos 5.2 drops some of those safeguards. Anthropic calls it “our most capable model for cybersecurity engineering”, and it’s only for vetted organisations through its Cyber Verification Program and Life Sciences Verification Program. Claude Enterprise customers also get it through Claude Security.
For everyday users, Fable 5.2 is the one you’ll see. If you do security work, expect Fable to refuse much of it.
How Does Claude Fable 5.2 Compare on Benchmarks?
These are Anthropic’s own figures, not my tests. A selection from its launch table:
| Benchmark | Fable 5.2 | Fable 5.1 | Opus 5.5 | GPT-6 Astra | Gemini 4 Carbon |
|---|---|---|---|---|---|
| FrontierSWE v2 (coding) | 69.9% | 56.3% | 62.3% | 65.5% | 61.2% |
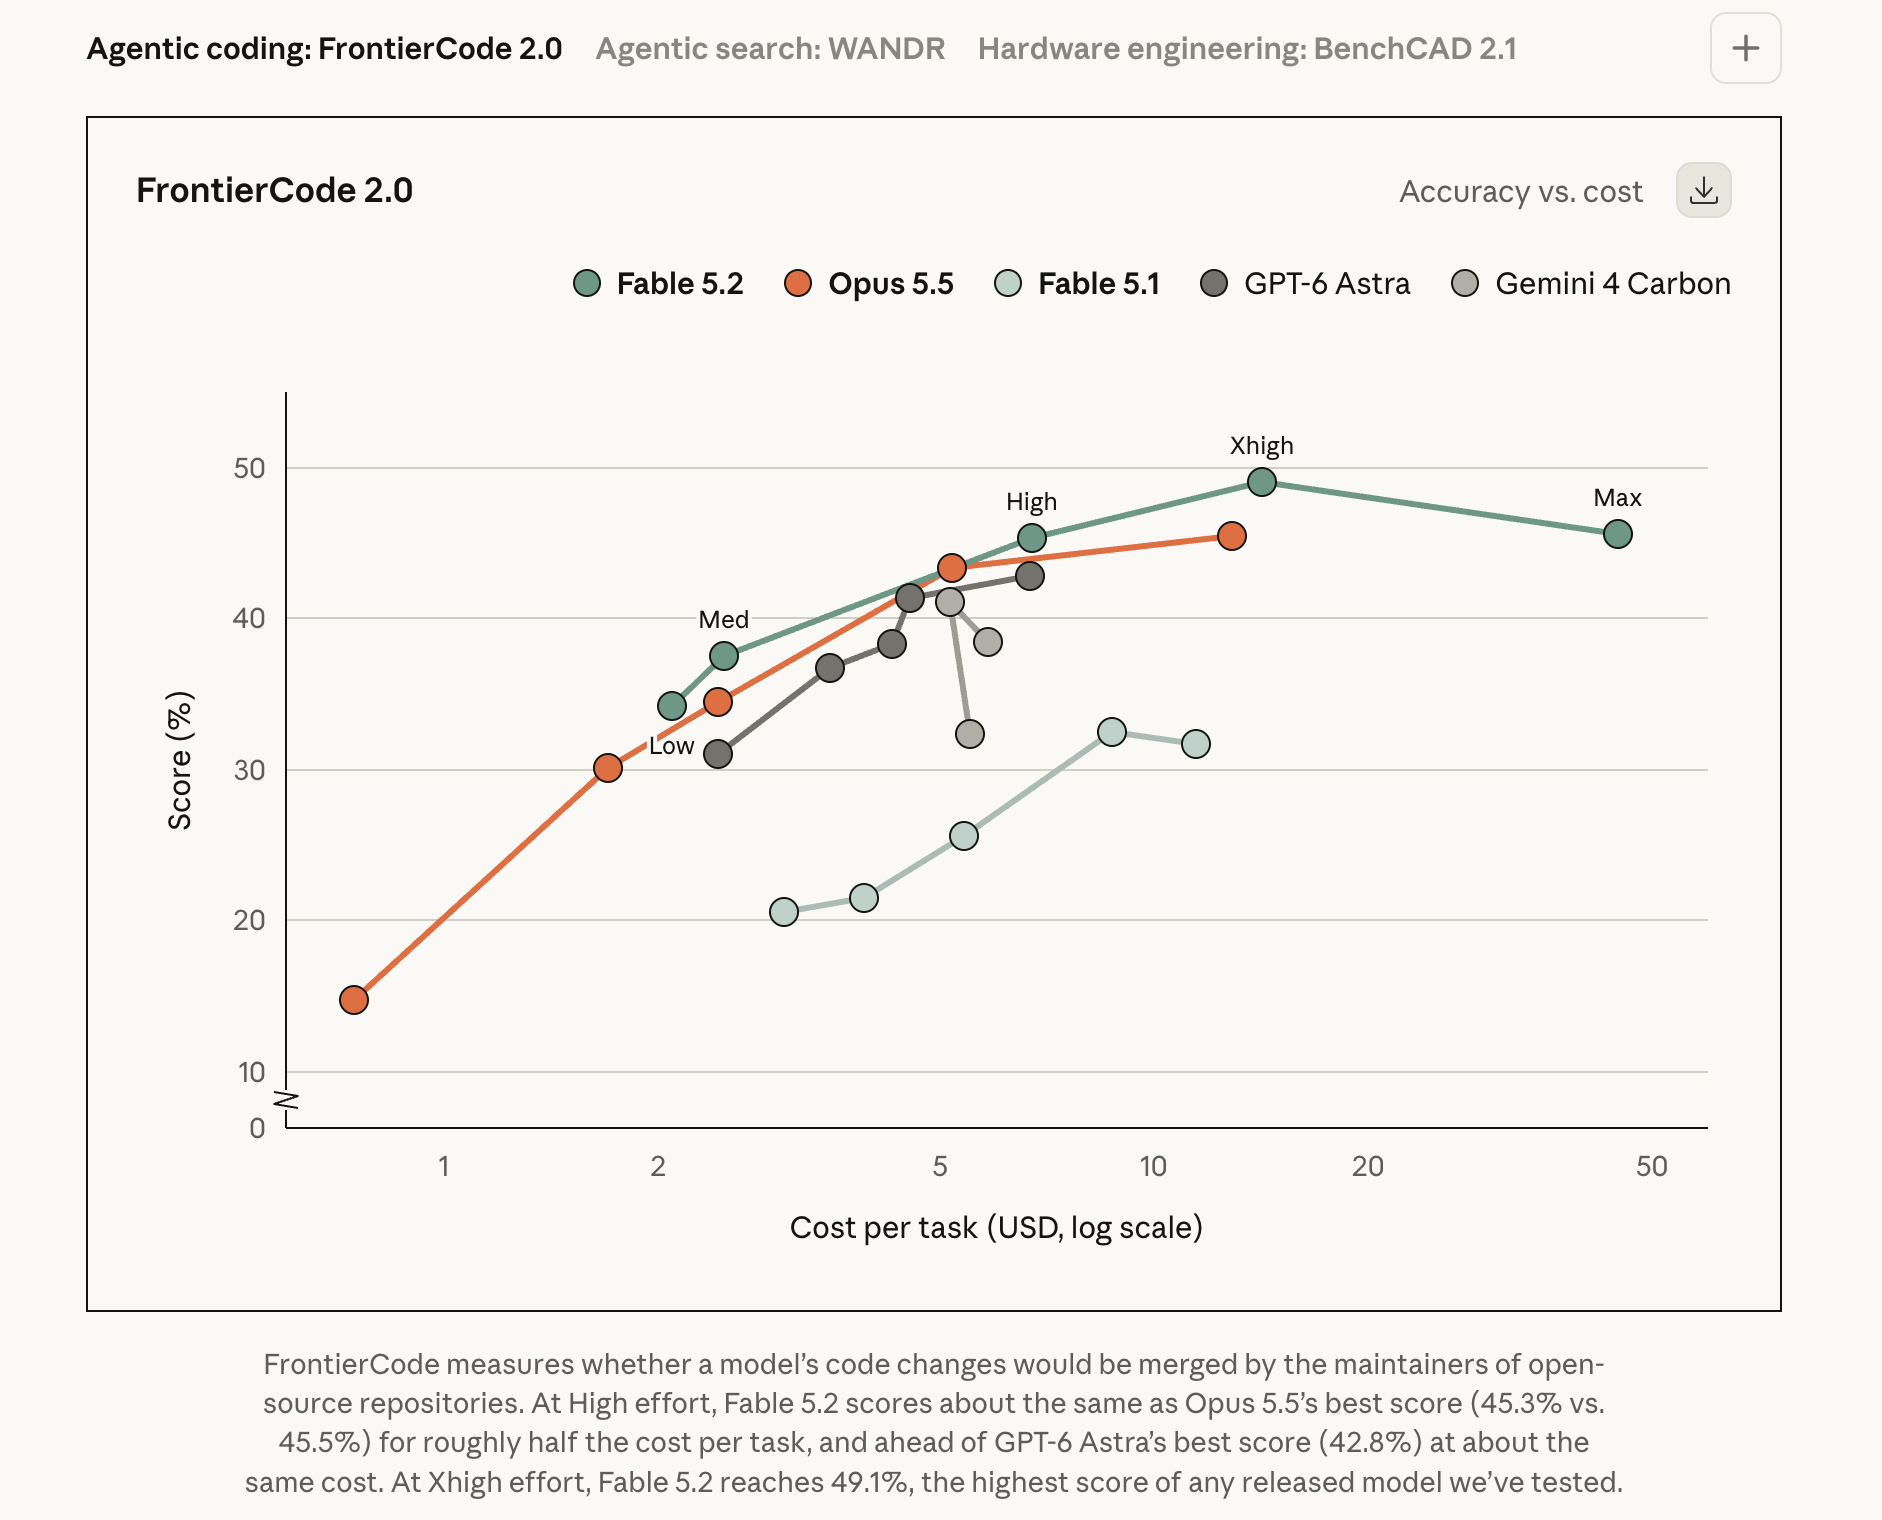
| FrontierCode 2.0 | 49.1% | 32.4% | 45.5% | 42.8% | 41.1% |
| OSWorld 2.1 (computer use) | 89.3% | 83.5% | 87.2% | 79.5% | 81.5% |
| Humanity’s Last Exam (with tools) | 74.2% | 65.6% | 67.7% | 57.2% | — |
| AutomationBench | 51.4% | 31.4% | 42.5% | 41.4% | 53.9% |
Fable 5.2 leads on most rows, but not all: Google’s Gemini 4 Carbon scores higher on AutomationBench. The detail I found most useful is further down Anthropic’s page. On FrontierCode at high effort, Fable 5.2 scores 45.3% against Opus 5.5’s 45.5%, for “roughly half the cost per task”. So the cheaper-per-token model isn’t always the cheaper model per job.
Is Claude Fable 5.2 Safe?
Anthropic says “high-stakes risks from misalignment remain low”, and that the model did as well as or better than its recent models on most alignment measures. External testing included the UK AI Security Institute and METR. Anthropic has also published a system card with the full results. That’s the vendor’s assessment; I can’t check it independently.
Should Claude Users Switch to Fable 5.2?
Probably not for everything, and Anthropic agrees. Its own recommendation is to start with Opus 5.5, “our strongest daily driver”, and move up to Fable for demanding reasoning and long-running agent work. If you use Claude for writing, research and documents, Opus 5.5 is likely enough. Fable 5.2 is for big, open-ended jobs where the extra capability pays for itself.
On the paid Claude plans, Fable comes out of your usage limits. When I covered the Claude Ultra rename, Max and Ultra included Fable for up to half of the weekly limit, so check your usage settings before leaning on it for long jobs. I’ll test Fable 5.2 hands-on and update my Claude AI review.
Frequently Asked Questions
How much does Claude Fable 5.2 cost?
On the API, Claude Fable 5.2 costs $8 per million input tokens and $40 per million output tokens, or $16 and $80 in fast mode. That’s twice the price of Claude Opus 5.5. In the Claude apps it’s used within your plan’s limits.
Is Claude Fable 5.2 better than Opus 5.5?
On Anthropic’s benchmarks, Claude Fable 5.2 scores higher than Opus 5.5 on most tests. But Anthropic still recommends Opus 5.5 as the starting point for most coding and knowledge work, and Fable for the hardest, longest-running jobs.
Can I use Claude Mythos 5.2?
Only if your organisation is approved. Claude Mythos 5.2 is for vetted organisations in cybersecurity and life sciences, through Anthropic’s verification programmes, and for Claude Enterprise customers through Claude Security.
What is the Claude Fable 5.2 context window?
Claude Fable 5.2 has a 1 million-token context window and a maximum output of 128,000 tokens, according to Anthropic’s models overview.
More from WhatAITools: Claude AI review, ChatGPT vs Claude, Claude Fable 5.1 news and Claude Ultra news.
Leave a Reply